Westlaw Ruling Puts a Price on AI Training Material
A US appeals court has ruled that copying Westlaw headnotes to train a rival AI research tool was not fair use. Governments that license public data, buy AI and build legal tools now have a contract problem to fix.
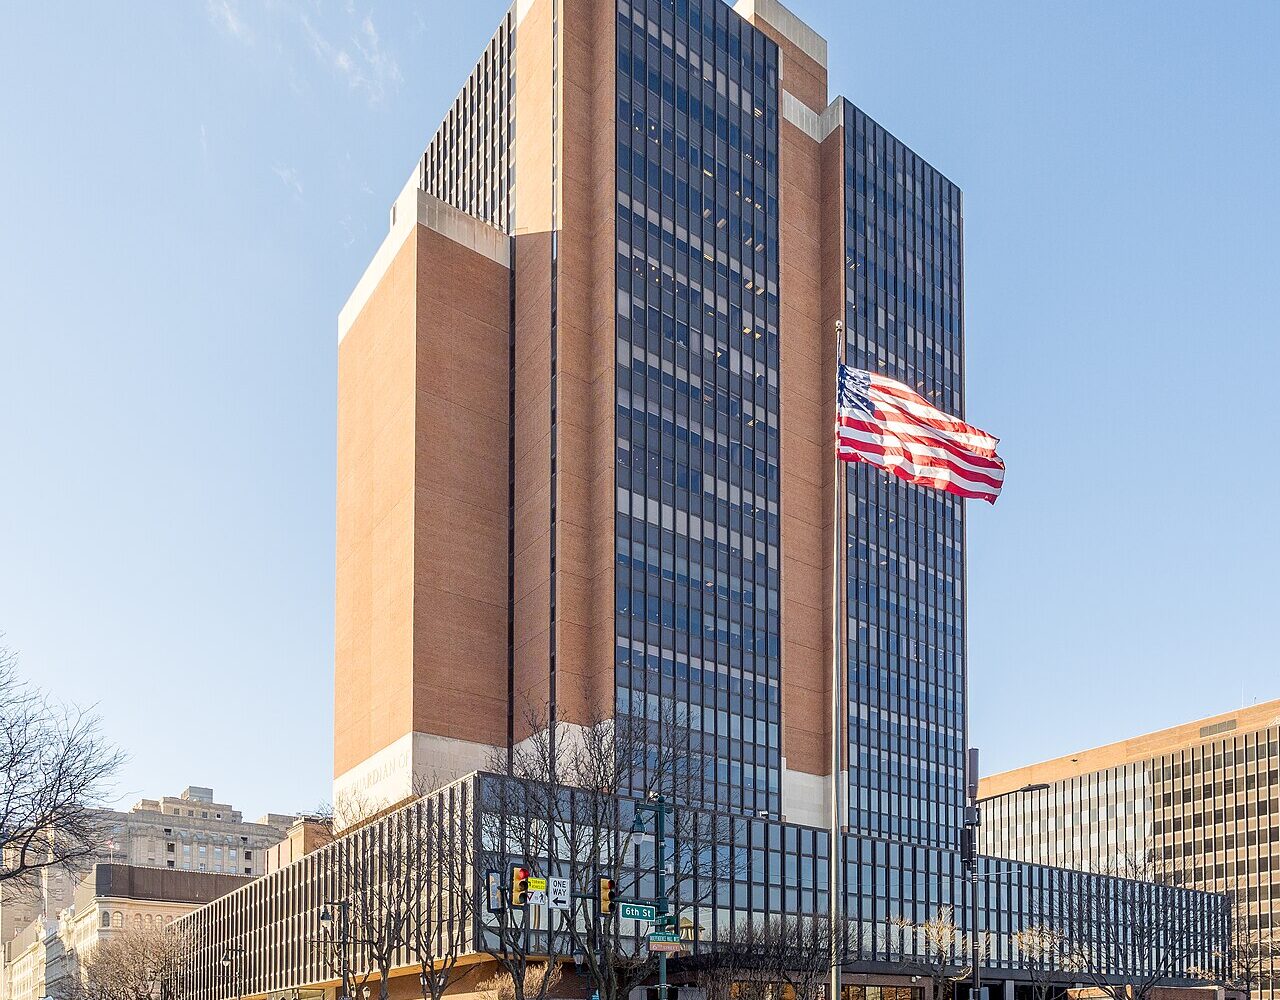
The James A. Byrne United States Courthouse in Philadelphia, seat of the US Court of Appeals for the Third Circuit.
Key points
- On 29 September 2026 the US Court of Appeals for the Third Circuit held that Westlaw headnotes are copyrightable and that ROSS Intelligence’s copying of 2,243 of them to train a non-generative legal-search tool was not fair use.
- The court found that a market for licensing headnotes to train AI is “rapidly developing” and that unlicensed copying usurped Thomson Reuters’s chance to enter it.
- On this desk’s reading, neither the main US federal AI-acquisition memo nor the General Services Administration’s new LLM clause requires a warranty on vendors’ own training data; EU law requires a published training-content summary.
What MediaPost called apparently the first appellate ruling on whether AI companies may train on other publishers’ content has gone against the copier. In Thomson Reuters Enterprise Centre GmbH v ROSS Intelligence Inc, No. 25-2153, the Third Circuit affirmed partial summary judgment for the owner of Westlaw. The tool was narrow and non-generative, but the reasoning on market harm reaches every public body that owns curated text, buys AI trained on others’ text, or wants cheaper legal research.
Headnotes Are Protected, and a Lost Licensing Market Counts as Harm
Judges Restrepo, Montgomery-Reeves and Bove heard the interlocutory appeal on 11 June 2026; Judge Montgomery-Reeves wrote the opinion. Circuit Judge Stephanos Bibas, sitting by designation in the District of Delaware, had ruled for Thomson Reuters in February 2025. The opinion was first filed under seal, MediaPost reported. The court lists it among its recent precedential opinions, with a public filing date of 30 September, so it binds federal courts across the circuit.
ROSS enlisted a contractor, LegalEase, which wrote about 25,000 training memos whose legal questions drew on Westlaw headnotes. The system wrote nothing new; it returned passages from roughly ten million public judicial opinions. Each headnote, the court held, reflected editorial choices about which points of law to state and how, enough for copyright; opinions remain free.
Three of the four fair-use factors went against ROSS. The use was commercial and “minimally transformative, at best”, since both firms used headnotes to help researchers find case law. ROSS said it took only 0.08 per cent of 28 million headnotes; the court replied that each headnote is a work in its own right and that copying was unnecessary when the opinions were freely available. “Unlike necessity, ease is not a justification for copying,” it wrote. Only the factual nature of headnotes favoured ROSS, slightly.
On the fourth factor, Thomson Reuters had not licensed headnotes to others for AI training. That did not matter: the evidence showed a licensing market that is “rapidly developing”, Thomson Reuters was training its own AI search products on the material, and ROSS had usurped its chance to enter that market.
Maria Pallante, chief executive of the Association of American Publishers, which filed an amicus brief for Thomson Reuters, said in the association’s statement: “Rightsholders are entitled to equitable participation in the AI market”. Dave Hansen of the non-profit Authors Alliance argued that the court ignored the circularity of finding harm to a market defined by the very use in dispute, and warned: “Rightsholders will cite its acceptance of an unlicensed, thinly evidenced AI training market.”
Washington’s Lawyers Are Already on the Record, Elsewhere
A footnote matters to governments. The court notes that the Department of Justice filed a statement of interest on generative AI on 1 September 2026 in In re: OpenAI, Inc. Copyright Infringement Litigation (No. 1:25-md-3143), pending in the US District Court for the Southern District of New York. As the court summarises it, the DOJ contended that training a large language model able to generate original responses is a transformative use, and that the training in that case did not lead to “substitutive competition”. The panel said those concerns did not apply to ROSS, whose tool cannot generate original expression, and remarked that the DOJ “notably did not” weigh in here. The footnote is this desk’s only account of the filing, which concerns one pending generative-AI case; the appellate ruling concerns different technology.
The US Copyright Office’s report on generative AI training, issued in pre-publication form in May 2025, sits between the two. It judged various training uses likely to be transformative, but placed mass commercial copying to produce competing expressive content, especially from illegally accessed sources, outside established fair-use boundaries, and preferred voluntary licensing to legislation.
For governments as owners of text, the court restated that work by officials speaking with the force of law cannot be copyrighted, while annotations by authors without that authority can be. Public bodies that commission summaries, annotated codes or guidance digests should settle who owns them and whether they may be licensed, or withheld, as training data.
Procurement Rules Guard the State’s Data, Not the Vendor’s
US purchasing rules look elsewhere. OMB Memorandum M-25-22, issued on 3 April 2025, tells agencies to define intellectual-property rights between government and contractor and to bar vendors permanently from using non-public agency inputs and outputs to train publicly or commercially available models without consent. The General Services Administration’s clause GSAR 552.239-7001, dated September 2026 and covered in this issue’s explainer on the GSA LLM clause, lists training on government data as a prohibited use and confirms the contractor keeps ownership of its base models.
In this desk’s reading, neither document asks a vendor to warrant that its own training material was lawfully obtained or licensed. That gap has a federal price. Under 28 U.S.C. § 1498(b), when a contractor infringes copyright for the government with its authorisation or consent, the owner’s only remedy is a suit against the federal government in the Court of Federal Claims. Whether pre-contract training is covered is untested; a model fine-tuned under contract on third-party material is the obvious candidate.
A buyer that protects its own data but asks nothing about the vendor’s is pricing only half the risk.
Brussels Asks for Disclosure Where Washington Leaves It to Courts
The EU starts from statute. Article 53(1)(c) of the EU AI Act, Regulation (EU) 2024/1689, requires general-purpose model providers to adopt a policy to comply with EU copyright law, including honouring rightholders’ opt-outs from the text-and-data-mining exception. Article 53(1)(d) requires a public summary of training content on a template from the AI Office. The Commission’s template, published on 24 July 2025, asks for the top 10 per cent of scraped domain names and a description of opt-out measures; models released before 2 August 2025 have until 2 August 2027. Article 101 fines of up to 3 per cent of worldwide turnover or €15m have applied since 2 August 2026, as AI & GPP reported on the AI Office’s enforcement powers.
A targeted Commission consultation, opened on 29 September 2026 and closing on 3 November, covers “the use of copyright-protected content in artificial intelligence” and invites national authorities to respond.
The table below, built from the opinion and official texts, shows where each regime stands and what buyers can ask for now.
| Jurisdiction | Rule on copying for training | Source | What a public buyer should require |
|---|---|---|---|
| US, Third Circuit | Copying to train a competing non-generative tool is not fair use; lost training-licence market counts as harm | Opinion, No. 25-2153 | Licensed-data warranty; IP indemnity |
| US, generative models | Unsettled; per the court, DOJ argued transformative use in one pending case; Copyright Office says it depends on use and substitution | Opinion n. 7; Copyright Office Part 3 | Data-source disclosure; notice of infringement claims |
| US federal procurement | No training on government data; silent on vendor’s own data | M-25-22; GSAR 552.239-7001 | Add provenance warranty and indemnity |
| European Union | Providers must honour mining opt-outs and publish a training summary | AI Act Art. 53(1)(c)–(d); Commission template | Summary and copyright policy as tender conditions |
What Public Buyers Should Do Now
First, add a training-data warranty and an IP indemnity to AI contracts, above all for retrieval and legal-research tools built on a curated corpus, the fact pattern the court addressed. Second, inventory the annotated text the organisation owns or commissions and set its licensing terms before a vendor does. Third, require suppliers’ EU training summaries and copyright policies at tender. Watch whether ROSS acts on its stated intention, voiced through its counsel and reported by LawNext, to seek Supreme Court review; watch, too, the New York generative-AI litigation and the Brussels consultation after 3 November.
Questions This Answers
Is training an AI model on copyrighted material fair use in the US?
Not always. The Third Circuit held that copying Westlaw headnotes to train a competing, non-generative legal-search tool was not fair use. It distinguished generative models, which remain before other courts.
Do US federal AI contracts protect agencies against copyright claims over a vendor’s training data?
Not expressly. OMB M-25-22 and the GSA LLM clause bar vendors from training on government data, but neither requires a warranty about the vendor’s own training material. Buyers must add one.
What does EU law require AI model providers to disclose about training data?
Under Article 53 of the AI Act, general-purpose model providers must keep a copyright policy and publish a training-content summary on the Commission’s template, including the most-scraped domain names.
Sources
- Thomson Reuters Enterprise Centre GmbH v. ROSS Intelligence Inc, No. 25-2153, Opinion of the Court — US Court of Appeals for the Third Circuit — Filed 29 September 2026; (PDF)
- Recent Precedential Opinions — US Court of Appeals for the Third Circuit — listing “Filed 09/30/2026, No. 25-2153”; accessed 10 October 2026; rolling weekly page
- Appeals Court Sides With Thomson Reuters In Battle Over AI Training — MediaPost — 29 September 2026
- Association of American Publishers Welcomes the Third Circuit Decision in Favor of Plaintiff in Thomson Reuters v. ROSS Intelligence — Association of American Publishers — 1 October 2026; interested party (amicus for Thomson Reuters)
- Third Circuit affirms in Thomson Reuters v. ROSS: The Court Gets Merger Wrong and Does a Disservice to Fair Use — Authors Alliance — 2 October 2026; advocacy organisation
- Copyright and Artificial Intelligence, Part 3: Generative AI Training (pre-publication version) — US Copyright Office — May 2025; (PDF)
- M-25-22, Driving Efficient Acquisition of Artificial Intelligence in Government — Office of Management and Budget — 3 April 2025; (PDF)
- RGO-2026-01, GSAR Class Deviations in Response to Executive Order 14275 (incl. 552.239-7001) — General Services Administration — memo 15 January 2026; clause dated September 2026; (PDF)
- 28 U.S. Code § 1498 — Patent and copyright cases — Legal Information Institute, Cornell Law School — current text; accessed 10 October 2026
- Regulation (EU) 2024/1689 (Artificial Intelligence Act) — EUR-Lex — Official Journal, 12 July 2024; text as adopted
- Explanatory Notice and Template for the Public Summary of Training Content for general-purpose AI models — European Commission — 24 July 2025
- Commission seeks feedback on challenges and way forward in the area of effect of technology on copyright — European Commission — 29 September 2026
- ROSS Says It Will Ask Supreme Court to Review 3rd Circuit Ruling for Thomson Reuters in Copyright Case — LawNext — 2 October 2026
Discussion
No comments yet. Start the conversation.