Reach Is Not Risk: Why View Counts Mislead Government Monitors
A Full Fact and University of Westminster study of 112 AI fakes finds that most of the million-view items carried limited harm potential. Monitoring teams that rank by reach are measuring the wrong thing.
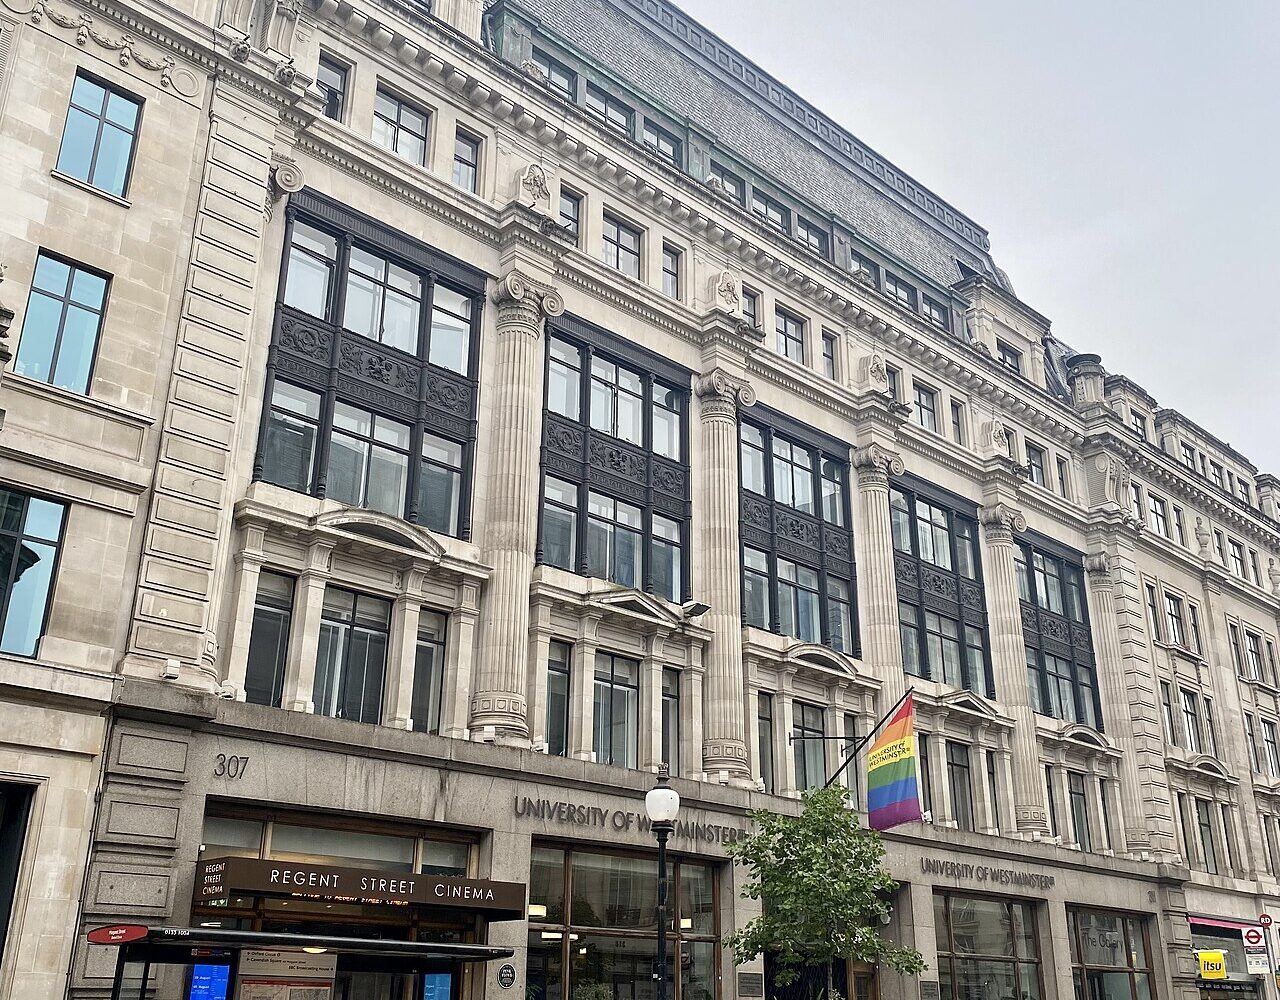
The University of Westminster's Regent Street building in London; the university partnered with Full Fact on the study (illustrative).
Photo: No Swan So Fine, CC BY-SA 4.0 · source
Key points
- Of 112 AI-generated or AI-altered false items fact-checked in the UK from 1 January 2025 to 31 March 2026, 94 (83.9%) created a substantively false understanding but only 46 (41.1%) had substantive potential for specific real-world harm.
- Of the 22 items that reached one million views or more, more than half had no or limited harm potential, according to the study.
- The study’s harm model tests falsity, belief and believers’ capacity to act, and the UK government’s RESIST 3 guidance says goal, impact and reach together should set priority.
Government media-monitoring dashboards tend to rank the day’s falsehoods by the one number platforms supply freely: views. A study published on 5 October 2026 by the UK fact-checking charity Full Fact and the University of Westminster suggests that number is a poor guide to what deserves a minister’s attention. Full Fact’s summary of the work, funded through the UK AI Security Institute’s Challenge Fund, describes a “potentially fairly weak link between virality and harm”. For officials rationing rebuttal and regulatory capacity, and for the analysts who triage for them, it offers evidence and a usable method.
What the Full Fact Study Counted, and What It Found
The report, AI-Generated Misinformation in the UK: Harm, Context, and Classification, examines 112 Full Fact fact checks and articles about AI-generated or AI-altered content published from 1 January 2025 to 31 March 2026. A version by Peter Cunliffe-Jones, Joseph O’Leary, David Corney and Andrew Dudfield is an arXiv preprint, 2610.06084, not yet peer reviewed. The AI Security Institute’s Challenge Fund, opened on 5 March 2025, awards up to £200,000 per project and lists societal resilience among its fields. The headline figures, from the report itself:
| Measure | Count | Share of 112 |
|---|---|---|
| Created a substantively false or misleading understanding | 94 | 83.9% |
| Only narrowly inaccurate | 18 | 16.1% |
| Substantive potential for specific real-world harm | 46 | 41.1% |
| No or limited harm potential | 66 | 58.9% |
| Reached one million views or more | 22 | 19.6% |
Confirmed or suspected AI claims made up 24 per cent of Full Fact’s checks in the period, against 8 per cent a year earlier. Volume is rising; the study’s point is that volume and risk differ.
Why a Million Views Can Mean Little and a Few Thousand a Lot
The report explains why the 66 low-harm items fell short. In 17 cases the claim was only narrowly inaccurate (the report classes 18 items as narrowly inaccurate overall but gives 17 here); in 19 the topic was inconsequential; in 24 too few people believed it; in the remaining six, believers lacked the capacity or motivation to act. An AI video of Hurricane Melissa convinced many viewers, but most of them lived outside the storm’s track and could do nothing with it.
The reverse case matters as much. Full Fact notes that an AI-faked clip showing an MP switching to Reform UK drew far fewer views than the viral items, yet surfaced at Prime Minister’s Questions. The report also recalls South Africa in 2000, when a fringe claim that HIV does not cause AIDS reached President Thabo Mbeki and shaped national health policy. The question, the report argues, is whether a claim reaches the person able to act on it, not how many scroll past.
In this desk’s reading, that inverts the logic of the engagement dashboard, as argued in Beyond Dashboards. It also bears on election-season monitoring of synthetic political content, examined in Slopaganda and in this issue’s look at Africa’s election AI rules.
A view count tells a monitoring team how loud a falsehood is. It says almost nothing about whether anyone can, or will, act on it.
How the Harm Model Scores an Item
The method comes from Fake News – What’s the Harm?, Peter Cunliffe-Jones’s open-access book from University of Westminster Press (2025), built on 250 case studies and trialled from 2024 with Africa Check, AFP Fact Check and Full Fact. It asks three questions in sequence: is the resulting understanding substantively false or merely narrowly inaccurate; does it persuade enough people to produce a specific consequence; and can and will those believers act. Assessors worked through 14 evidence points, including audience size and nature, perceived credibility, repetition and fit with a conspiracy narrative.
Items passing all three gates are classified by harm field (eight, from unrest and vigilante violence, scams and health to conspiracy belief and political attitudes), by who is affected and by whether the effect is direct or cumulative. Of 78 potential consequences identified, 39 could affect all or much of society.
UK government guidance points the same way. The Government Communications framework RESIST 3, published on 29 October 2025, says “the goal, impact and reach should inform how urgently you prioritise the case”, rates risks for impact on public safety, public health and vulnerable audiences, and says government should not answer every false item. It adds that AI use alone does not signal a threat.
Worked Example: An Illustrative Harm-Triage Sheet
This desk wrote the sheet below to show how a monitoring team could apply the study’s logic. It is illustrative: items and figures are invented, and it describes no real government’s practice or dataset. Criteria A, C and D follow the Full Fact model’s three questions; B and E draw on its harm fields and RESIST 3’s impact areas. Each scores 0–2. Reach is a modifier: add 1 only if an item exceeds one million views and already scores 5 or more, so reach amplifies harm but cannot create it.
- A. Falsity: 0 accurate in substance or narrowly inaccurate; 1 misleading; 2 substantively false.
- B. Harm field: 0 inconsequential topic; 1 cumulative attitudinal field; 2 direct field (violence, health, scams, abuse, public safety).
- C. Belief: 0 evidence it is widely disbelieved; 1 mixed or unknown; 2 evidence of belief in the affected audience.
- D. Actionability: 0 believers cannot act; 1 indirect action only; 2 a clear, harmful step is available (pay, travel, stop treatment, confront).
- E. Target: 0 general public, no particular exposure; 1 specific group; 2 vulnerable group or a person positioned to decide.
| Illustrative item (invented) | Views (illustrative figures) | A | B | C | D | E | Core | Reach +1? | Priority |
|---|---|---|---|---|---|---|---|---|---|
| AI audio, posing as the local council, telling one estate’s residents that a flood evacuation is cancelled | 8,000 | 2 | 2 | 2 | 2 | 2 | 10 | No | 10 |
| Deepfake clinician urging diabetics to swap insulin for a supplement | 120,000 | 2 | 2 | 1 | 2 | 2 | 9 | No | 9 |
| AI image of an iceberg striking a cruise ship in the Pacific | 4,000,000 | 2 | 0 | 1 | 0 | 0 | 3 | No (core under 5) | 3 |
| Obvious AI clip of a fictional minister taxing garden gnomes | 1,500,000 | 1 | 1 | 0 | 0 | 0 | 2 | No (core under 5) | 2 |
Ranked by views, the viral items lead. Ranked by the sheet, the flood message comes first: its listeners are the people it can hurt. Teams copying the idea should log evidence and confidence behind each score, as RESIST 3 advises, and test scorers for consistency.
What the Sample Cannot Tell You
The 112 items are not a random sample: Full Fact selects claims for checkworthiness and mostly publishes definitive findings, so the shares above cannot be generalised to all AI content. Reach figures are likely underestimates because platforms restrict audience data and encrypted channels are opaque. The model identifies conditions for harm, not harm that occurred; an independent review at the University of Wisconsin-Madison noted the risk of inconsistent judgements, which the team met with a gold-standard review. And 22 high-reach items is a small base.
The report’s five recommendations to government are: backing for content credentials built into phones and cameras; mandatory automatic watermarking by generative AI firms serving UK users; interoperable provenance labelling building on SynthID and C2PA; a duty for the biggest platforms and search services to identify and curb risks to civic discourse, elections, public security and public health; and a researcher-access framework building on Ofcom’s July 2025 report under section 162 of the Online Safety Act 2023.
The practical step for decision-makers is smaller. Monitoring contracts and dashboards should stop using views as the ranking key and ask for falsity, belief, actionability and exposure alongside reach. Watch, too, whether ministers answer the call on researcher access, without which every team’s reach data stays partial.
Questions This Answers
Does going viral make AI misinformation more harmful?
Not reliably. In the Full Fact and University of Westminster report, more than half of the 22 items with one million or more views had no or limited potential for specific harm.
How should a government team prioritise AI-generated falsehoods?
Score falsity, belief, capacity to act, harm field and exposure, then treat reach as an amplifier. The UK’s RESIST 3 framework likewise says goal, impact and reach should together set urgency.
Can the study’s percentages be applied to all AI content online?
No. The sample comes from Full Fact’s published checks, chosen for checkworthiness; the arXiv version is a preprint not yet peer reviewed.
Sources
- What’s the harm? Fact checking reveals the true scale of AI fakery — Full Fact — 5 October 2026
- AI-Generated Misinformation in the UK: Harm, Context, and Classification — Full Fact / University of Westminster (AISI Challenge Fund) — date not shown on page (released alongside source 1, 5 October 2026)
- AI-Generated Disinformation in the UK: Risk of Harm, Context, and Classification (arXiv:2610.06084) — Cunliffe-Jones, O’Leary, Corney, Dudfield, arXiv — submitted 5 October 2026; preprint, not peer reviewed
- Fake News – What’s the Harm? — Peter Cunliffe-Jones, University of Westminster Press (Fulcrum) — 2025; open access
- RESIST 3: building resilience to information threats — Government Communications (UK) — 29 October 2025
- Researchers’ access to information from regulated online services — Ofcom, via GOV.UK — 9 July 2025 (Ofcom published 8 July 2025)
- Grants: Challenge Fund — AI Security Institute — undated; fund opened 5 March 2025
- University of Westminster trial examines the potential of misinformation to cause, and not cause, harm — University of Westminster — 2 February 2024
Discussion
No comments yet. Start the conversation.